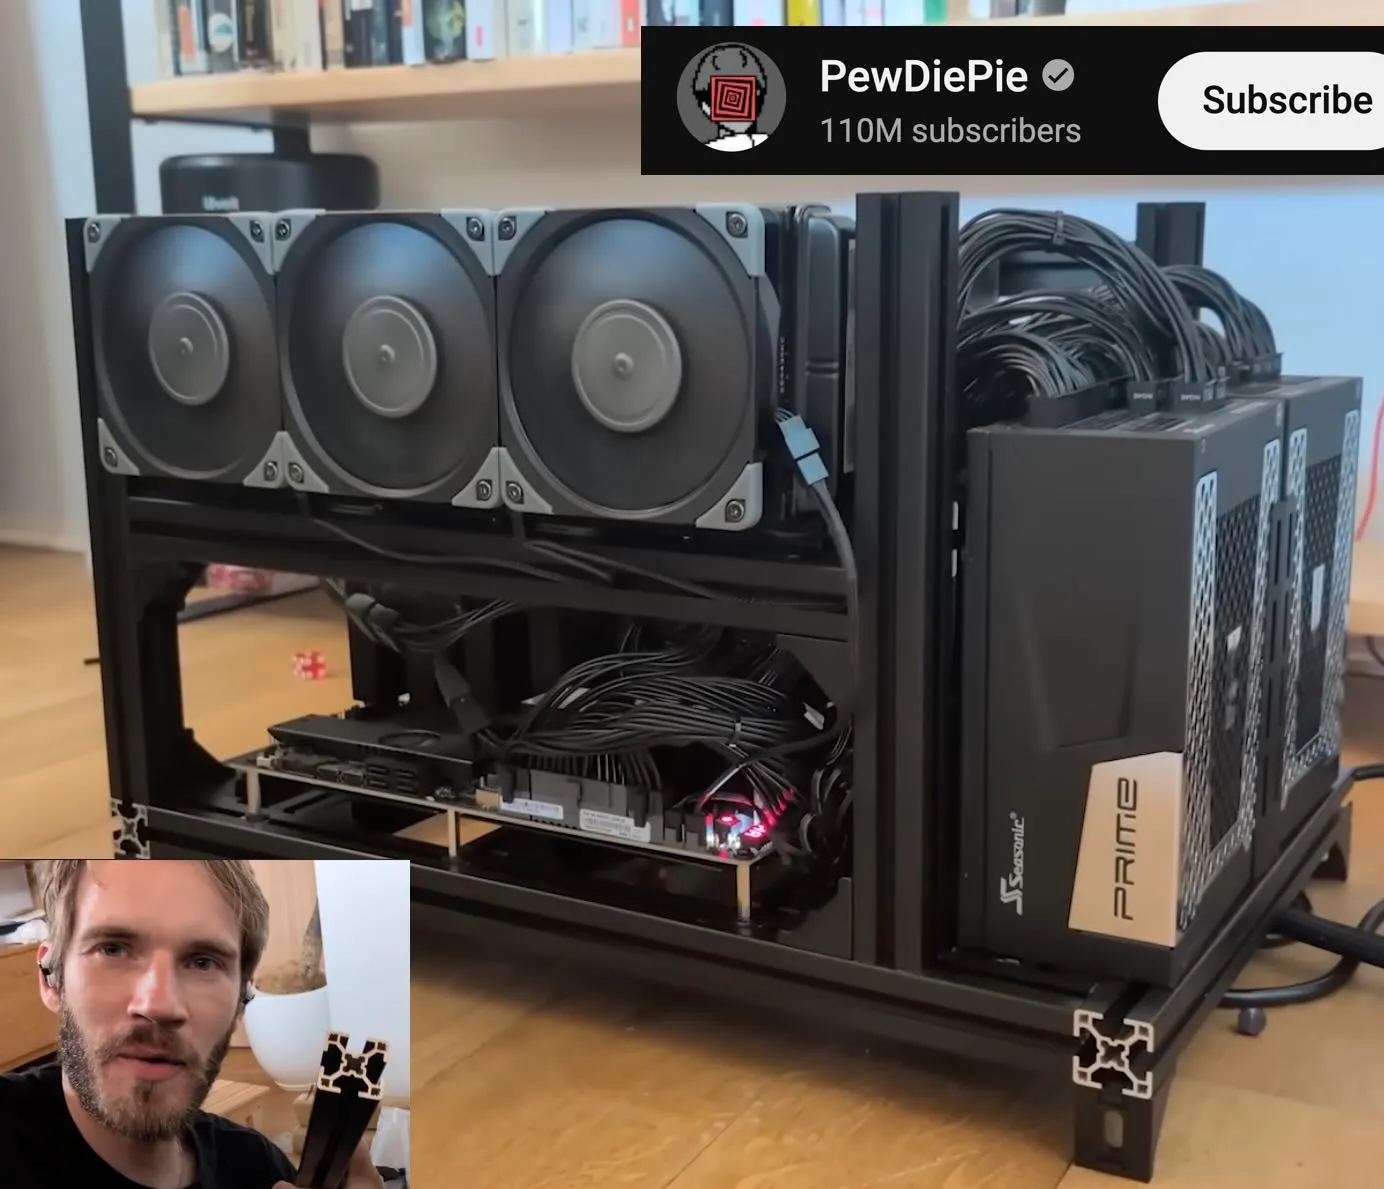
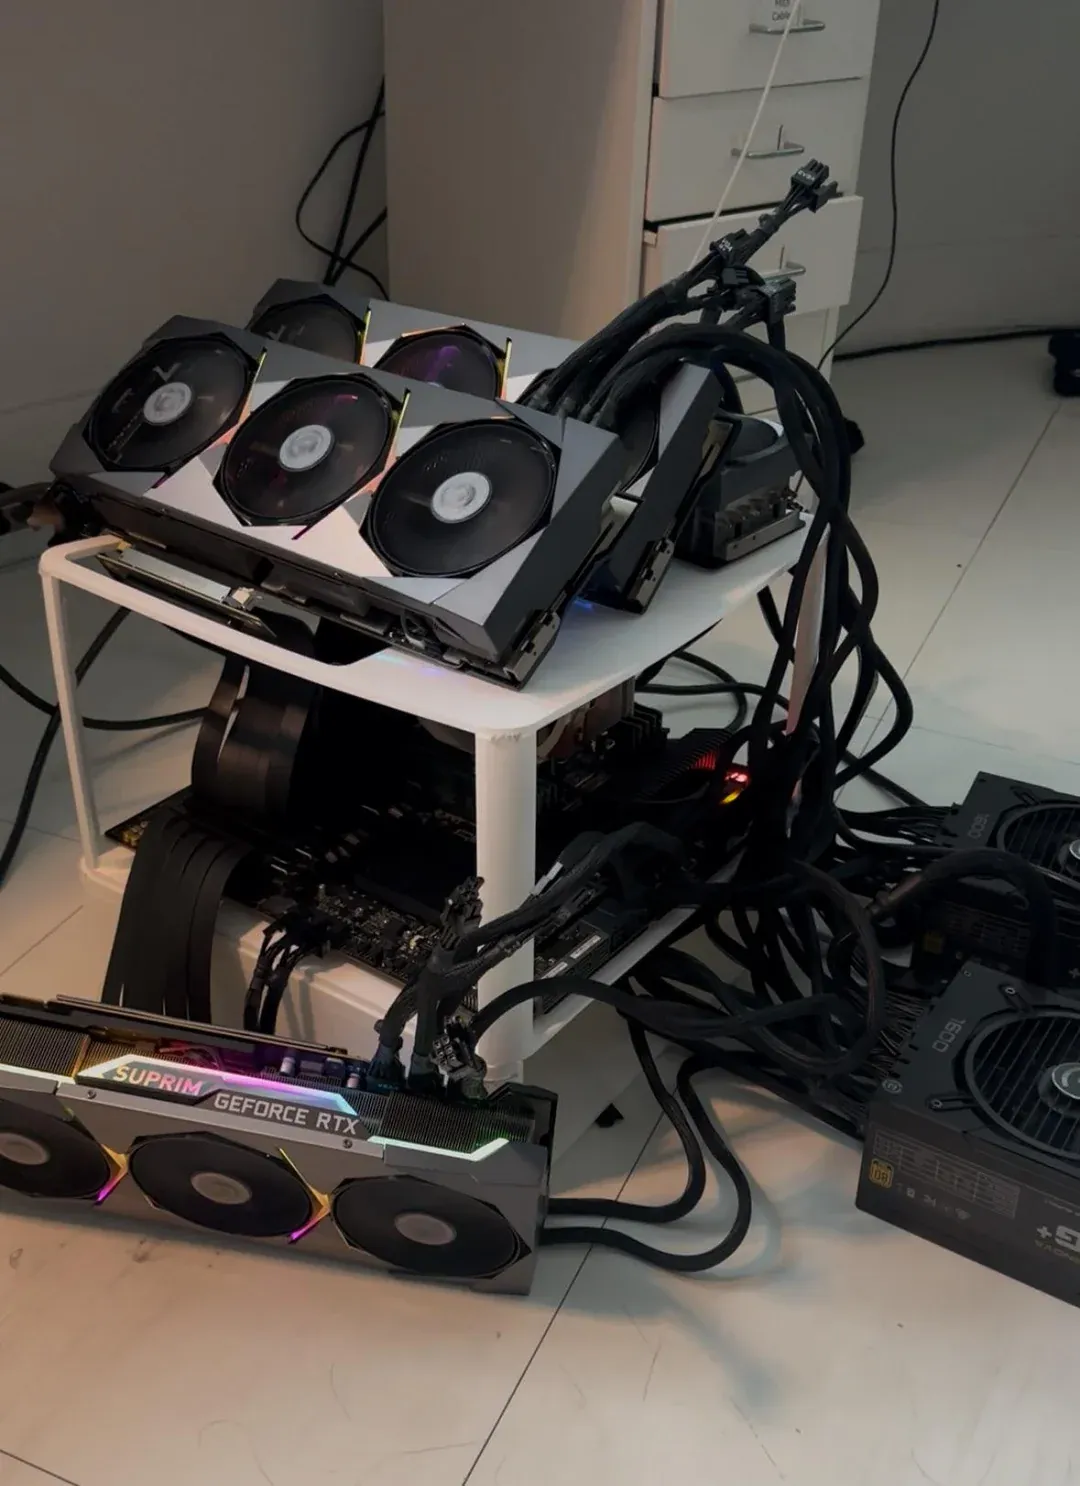
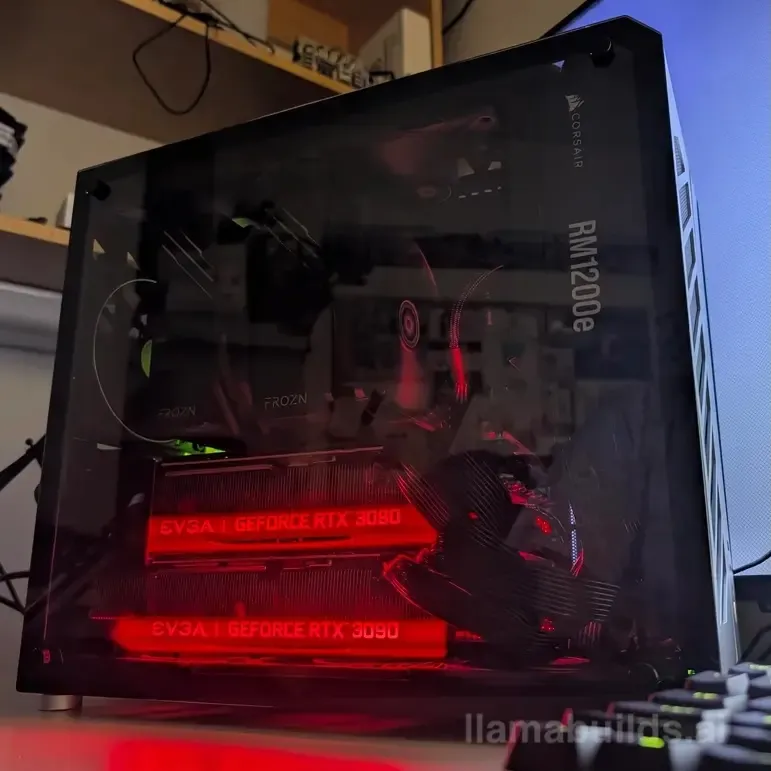
Server build · open-frame · New + used parts
The Machine
Enterprise ML server with 12x RTX 3090s
Built by fe2.net · Source: fe2.net: themachine · Updated
- Total cost
- $23,182
- VRAM
- 288GB
- GPUs
- 12
- System RAM
- 64GB
What can this build run?
With 288GB of VRAM across 12 GPUs, this build comfortably runs models up to GLM-5.3-Flash (Q5_K_M, ~15 tokens/sec).
Parts list
Every part in the The Machine
We may earn a commission when you buy through links on this page. It never changes what we recommend. How we make money
| Part | Price | Buy |
|---|---|---|
GPU 12×NVIDIA GeForce RTX 3090 | $10,200$850 each | eBay |
CPU AMD EPYC 7502P | $249 | eBay |
Motherboard ASRock ROMED8-2T | $740 | eBay |
CPU Cooler Noctua NH-U9 TR4-SP3 | $100 | Amazon |
Memory Hynix 64GB server RAM The original listing does not state how many modules this price covers. | $3,600 | eBay |
Storage SK hynix Platinum P41 2TB SSD | $129 | Amazon |
Power Supply EVGA SuperNOVA 1600 G+ | $1,047 | Amazon |
Accessories Add2PSU multiple power supply adapter | $18 | Amazon |
Accessories NVIDIA GeForce RTX NVLink HB Bridge | $320 | |
Accessories C-Payne PCIe SlimSAS host adapter | $2,640 | c-payne.com |
Accessories SlimSAS SFF-8654 8i cable (45cm) | $1,080 | c-payne.com |
Accessories SlimSAS SFF-8654 8i cable (75cm) | $1,680 | c-payne.com |
Accessories C-Payne SlimSAS PCIe Gen4 device adapter | $1,380 | eBay |
| Total | $23,182 |
Prices at time of build; check current prices.
Capability
Models this build runs well
Estimated for a single user with 8K context, with the model split across all GPUs (for example with llama.cpp). Best quantization that fits, ranked by our capability score.
Best overall · also coding, reasoning, vision, largest that fits
GLM-5.3-FlashQ5_K_M · ~15 tokens/sec
Runner-up
DeepSeek V4 FlashFP4 · ~19 tokens/sec
Fastest good model
Qwen3.5 9BQ8_0 · ~32 tokens/sec
| Model | Quant | Speed | Fit |
|---|---|---|---|
| GLM-5.3-Flash | Q5_K_M | ~15 tok/s | Runs well |
| DeepSeek V4 Flash | FP4 | ~19 tok/s | Runs well |
| Qwen3.8 27B | Q8_0 | ~17 tok/s | Runs well |
| Qwen3.5 122B-A10B | Q8_0 | ~17 tok/s | Runs well |
| Qwen3.6 35B-A3B | Q8_0 | ~24 tok/s | Runs well |
| Gemma 4 31B | Q8_0 | ~16 tok/s | Runs well |
| gpt-oss-120b | MXFP4 | ~25 tok/s | Runs well |
| Gemma 4 26B A4B | Q8_0 | ~23 tok/s | Runs well |
| GLM-4.5-Air | Q8_0 | ~15 tok/s | Runs well |
| gpt-oss-20b | MXFP4 | ~26 tok/s | Runs well |
The build
About this build
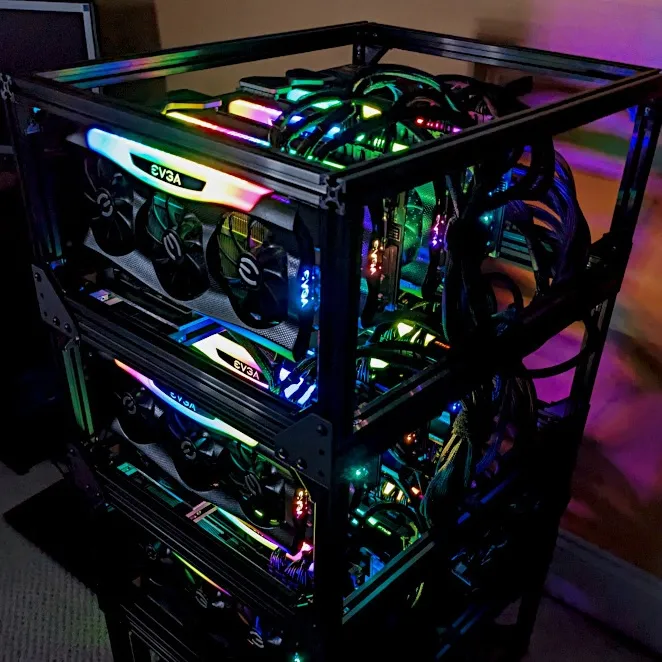
A 12x RTX 3090 open-frame server on an EPYC platform with 288GB of total VRAM, built to run several large models at once, including Llama 3.1 405B. The GPUs connect through C-Payne SlimSAS PCIe adapters.
Why this build
I’ve been fascinated by the potential of large language models to revolutionize the way we interact with technology. However, running these models requires serious computational horsepower. That’s why I set out to build a custom machine learning server, dubbed “themachine”, capable of running multiple LLMs concurrently and handling large context sizes.
The result is an enterprise-grade ML server with 12 RTX 3090s and 288GB of total VRAM. That’s enough to run several large models at the same time, including Llama-3.1-405B-Instruct, Mistral-Large-Instruct-2407, and more.
Notes and caveats
- A large share of the non-GPU budget goes to PCIe connectivity: C-Payne SlimSAS host adapters, SFF-8654 8i cables, and PCIe Gen4 device adapters.
- Power comes from EVGA SuperNOVA 1600 G+ units tied together with an Add2PSU adapter.
Source
Original write-up: themachine on fe2.net.
Specifications
Full specs
- GPU
- 12× RTX 3090
- CPU
- AMD EPYC 7502P
- Motherboard
- ASRock Rack ROMED8-2T
- Memory
- SK hynix 64GB server RAM
- Storage
- SK hynix Platinum P41 2TB NVMe SSD
- Power supply
- EVGA SuperNOVA 1600 G+ (linked with an Add2PSU adapter)
- Case
- Open-air multi-tier frame
- Cooling
- Noctua NH-U9 TR4-SP3
- Form factor
- open-frame
- GPU power
- 4,200W rated
Keep browsing