Server build · open-frame rack · New parts
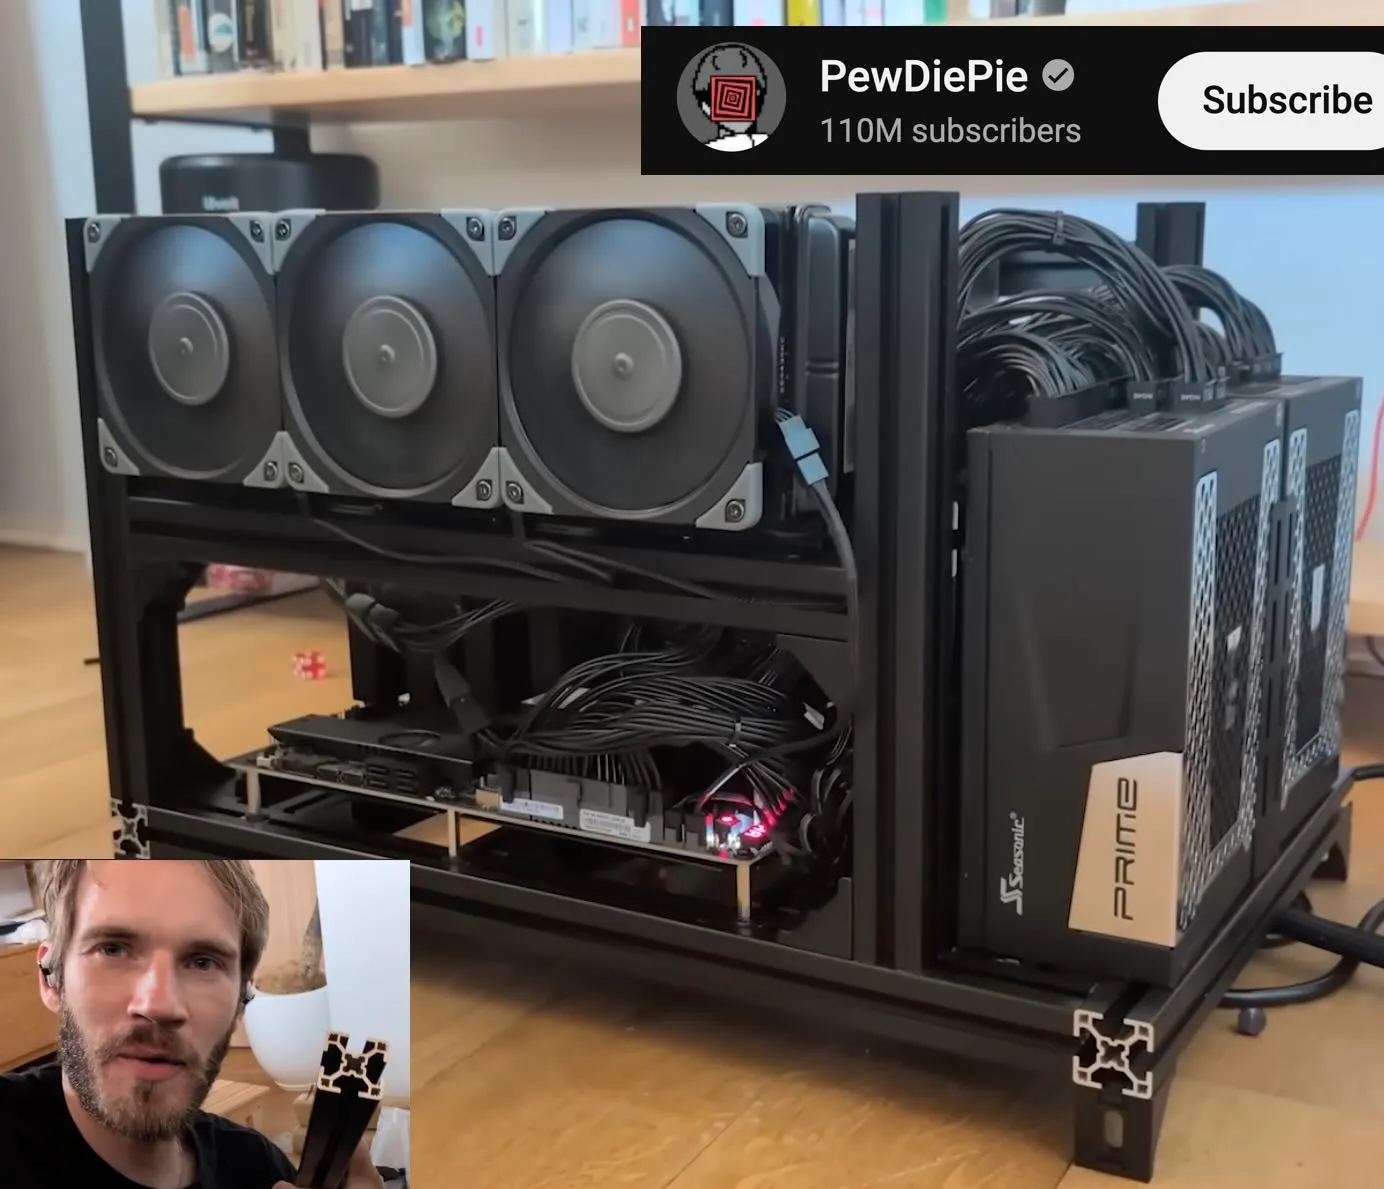
PewDiePie "Odysseus"
PewDiePie's first NVIDIA multi-GPU inference rig
Built by PewDiePie · Updated
- Total cost
- $20,429
- VRAM
- 140GB
- GPUs
- 7
- System RAM
- 192GB
What can this build run?
With 140GB of VRAM across 7 GPUs, this build comfortably runs models up to Qwen3.5 122B-A10B (Q6_K, ~15 tokens/sec). Our top all-round pick for it is Qwen3.6 35B-A3B at Q8_0 (~26 tokens/sec).
Parts list
Every part in the PewDiePie "Odysseus"
We may earn a commission when you buy through links on this page. It never changes what we recommend. How we make money
| Part | Price | Buy |
|---|---|---|
GPU 7×NVIDIA RTX 4000 Ada Generation | $11,200$1,600 each | Amazon |
Motherboard ASUS Pro WS WRX90E-SAGE SE EEB | $1,129 | Amazon |
CPU AMD Ryzen Threadripper PRO 7975WX | $4,650 | Amazon |
Memory 2×V-Color DDR5 96GB (4 x 24GB) 7600MHz CL38 | $2,400$1,200 each | Amazon |
Power Supply Seasonic Prime TX-1300 | $960 | Amazon |
Storage Samsung 990 PRO SSD 1TB | $90 | Amazon |
Case Custom aluminum open rack | — | |
| Total | $20,429 |
Prices at time of build (2025); check current prices.
Capability
Models this build runs well
Estimated for a single user with 8K context, with the model split across all GPUs (for example with llama.cpp). Best quantization that fits, ranked by our capability score.
Best overall · also coding, reasoning, vision
Qwen3.6 35B-A3BQ8_0 · ~26 tokens/sec
Runner-up · also largest that fits
Qwen3.5 122B-A10BQ6_K · ~15 tokens/sec
Fastest good model
gpt-oss-20bMXFP4 · ~30 tokens/sec
| Model | Quant | Speed | Fit |
|---|---|---|---|
| Qwen3.6 35B-A3B | Q8_0 | ~26 tok/s | Runs well |
| Qwen3.5 122B-A10B | Q6_K | ~15 tok/s | Runs well |
| gpt-oss-120b | MXFP4 | ~28 tok/s | Runs well |
| Gemma 4 26B A4B | Q8_0 | ~23 tok/s | Runs well |
| Qwen3.8 27B | Q8_0 | ~9.0 tok/s | Runs well |
| Gemma 4 31B | Q8_0 | ~8.2 tok/s | Runs well |
| gpt-oss-20b | MXFP4 | ~30 tok/s | Runs well |
| Qwen3.5 9B | Q8_0 | ~22 tok/s | Runs well |
| GLM-4.5-Air | Q8_0 | ~11 tok/s | Runs well |
| Gemma 4 E4B | Q8_0 | ~24 tok/s | Runs well |
The build
About this build
PewDiePie's open-rack inference rig runs seven RTX 4000 Ada cards on a Threadripper PRO platform for 140GB of total VRAM. It is a little rough around the edges, but a great example of why big multi-GPU builds move to open frames.
Why this build
PewDiePie, best known for his gaming content, recently got into Linux and local AI. His build might be a bit rough around the edges, but it’s incredibly cool to see such an influential creator join the local AI community and build something this big.
There’s room for improvement, particularly around storage and motherboard selection (bifurcation compatibility, for example). Still, this is an impressive build and a great showcase of why so many enthusiasts move to open-rack “miner” frames once a build uses more than four GPUs.
Notes and caveats
Given that PewDiePie had a practically unlimited budget, it’s curious that he chose the middle-of-the-road NVIDIA RTX 4000 Ada. It’s essentially an RTX 4070-class chip with workstation drivers and 20GB of memory. We hope he reads this and picks some more powerful or more cost-effective GPUs in the near future.
Specifications
Full specs
- GPU
- 7× RTX 4000 Ada
- CPU
- AMD Ryzen Threadripper PRO 7975WX
- Motherboard
- ASUS Pro WS WRX90E-SAGE SE (EEB)
- Memory
- 192GB DDR5-7600 CL38 (2x V-Color 96GB kits)
- Storage
- Samsung 990 Pro 1TB SSD
- Power supply
- Seasonic Prime TX-1300
- Case
- Custom aluminum open rack
- Form factor
- open-frame rack
- GPU power
- 910W rated
Keep browsing
Similar builds
 $23,182
Server · 288GB VRAM
The Machine
Enterprise ML server with 12x RTX 3090s
12× RTX 3090
 $10,397
Workstation · 48GB VRAM
Professional AI Workstation
High-end single-GPU workstation
RTX 6000 Ada
 $43,568
Workstation · 384GB VRAM
a16z Personal AI Workstation
Cutting-edge 4x RTX Pro 6000 Blackwell workstation
4× RTX PRO 6000