High-end build · open-frame · Used parts
FJÄLLBO
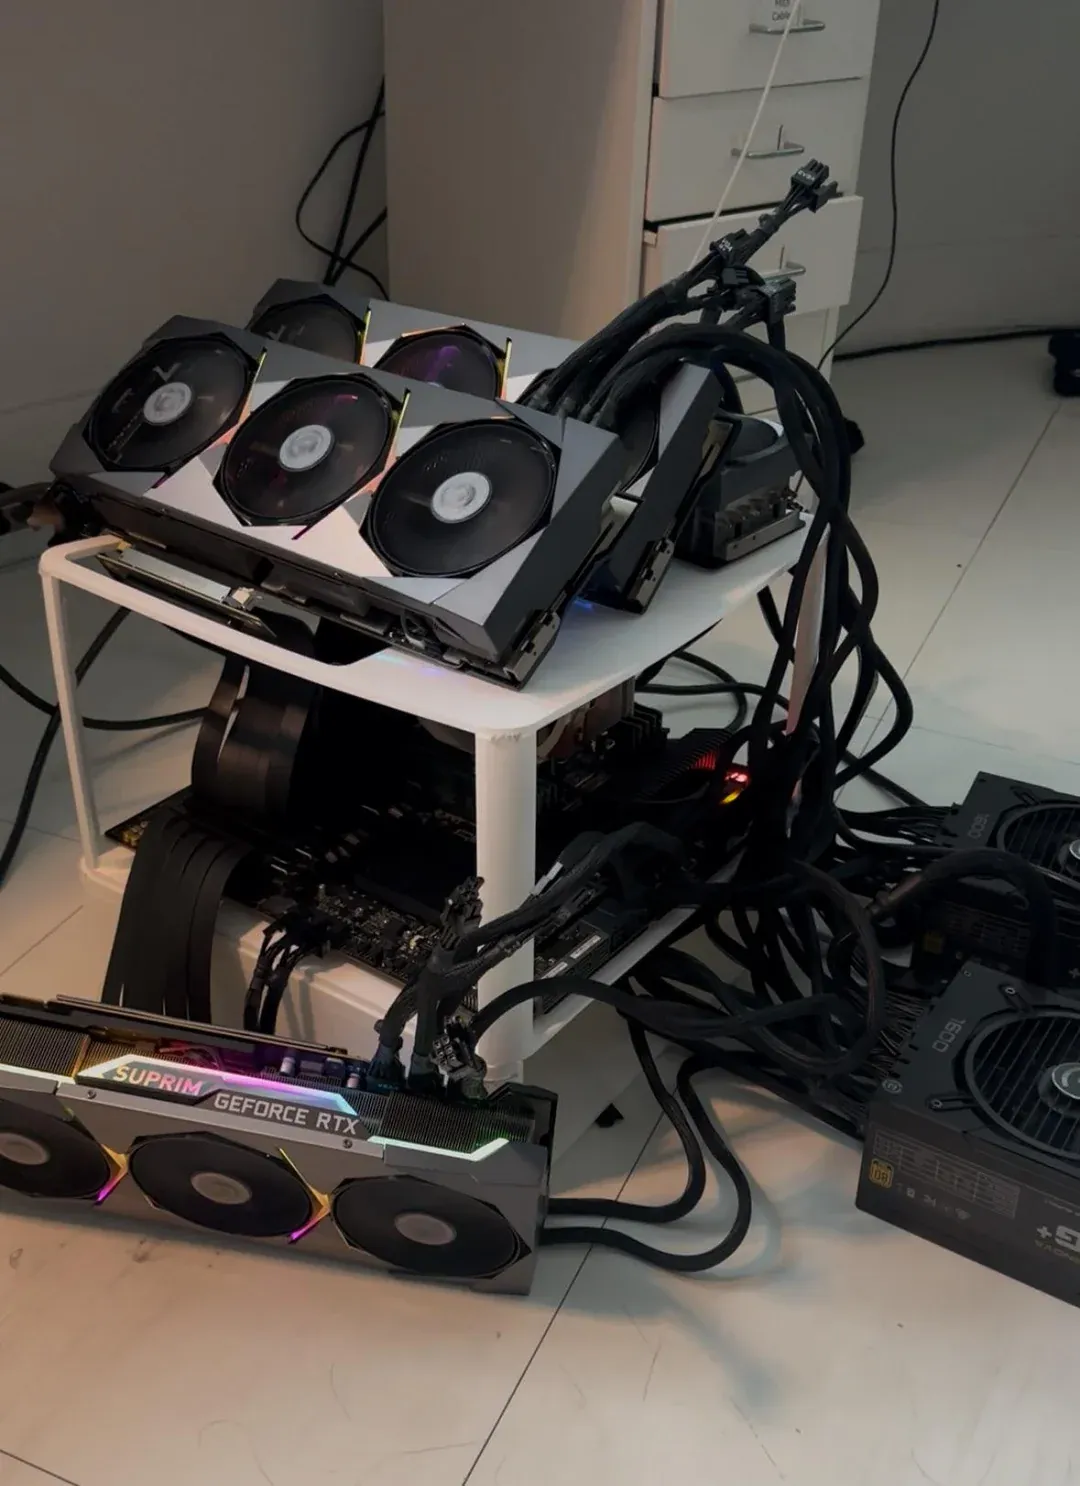
AI workstation arranged on an IKEA table
Built by r/LocalLLaMA community member · Source: r/LocalLLaMA: 4x 3090 local AI workstation · Updated
- Total cost
- $6,486
- VRAM
- 96GB
- GPUs
- 4
- System RAM
- 128GB
What can this build run?
With 96GB of VRAM across 4 GPUs, this build comfortably runs models up to Qwen3.5 122B-A10B (Q4_K_M, ~39 tokens/sec). Our top all-round pick for it is Qwen3.8 27B at Q8_0 (~21 tokens/sec).
Parts list
Every part in the FJÄLLBO
We may earn a commission when you buy through links on this page. It never changes what we recommend. How we make money
| Part | Price | Buy |
|---|---|---|
GPU 4×NVIDIA GeForce RTX 3090 (used) | $3,400$850 each | eBay |
CPU AMD Ryzen Threadripper PRO 3955WX | $600 | Amazon |
CPU Cooler ARCTIC Liquid Freezer III | $89 | Amazon |
Motherboard ASUS Pro WRX80E-SAGE | $1,199 | Amazon |
Memory Remix Ram DDR4 128GB | $456 | Amazon |
Storage Samsung 980 Pro 2TB M.2-2280 NVMe SSD | $199 | Amazon |
Case IKEA FJÄLLBO table | $45 | |
Power Supply CORSAIR HX1500i 1500W | $698 | Amazon |
| Total | $6,486 |
Listed prices from 2025; check current prices. The builder paid about $4,300 in total by buying everything used. Individual parts add up to $6,686.
Capability
Models this build runs well
Estimated for a single user with 8K context, with the model split across all GPUs (for example with llama.cpp). Best quantization that fits, ranked by our capability score.
Best overall · also coding, reasoning, vision
Qwen3.8 27BQ8_0 · ~21 tokens/sec
Runner-up · also largest that fits
Qwen3.5 122B-A10BQ4_K_M · ~39 tokens/sec
Fastest good model
gpt-oss-20bMXFP4 · ~60 tokens/sec
| Model | Quant | Speed | Fit |
|---|---|---|---|
| Qwen3.8 27B | Q8_0 | ~21 tok/s | Runs well |
| Qwen3.5 122B-A10B | Q4_K_M | ~39 tok/s | Runs well |
| Qwen3.6 35B-A3B | Q8_0 | ~52 tok/s | Runs well |
| Gemma 4 31B | Q8_0 | ~19 tok/s | Runs well |
| gpt-oss-120b | MXFP4 | ~56 tok/s | Runs well |
| Gemma 4 26B A4B | Q8_0 | ~48 tok/s | Runs well |
| GLM-4.5-Air | Q5_K_M | ~31 tok/s | Runs well |
| gpt-oss-20b | MXFP4 | ~60 tok/s | Runs well |
| Qwen3.5 9B | Q8_0 | ~48 tok/s | Runs well |
| Gemma 4 E4B | Q8_0 | ~53 tok/s | Runs well |
The build
About this build
Four used RTX 3090s on an open IKEA table give this Threadripper PRO rig 96GB of VRAM for running 70B-class models locally. The builder bought every part on the used market for about $4,300.
Why this build
I bought everything on the used market, about $4,300 in total, and got 96GB of VRAM. I’m currently considering picking up two more 3090s and maybe one 5090, but I think the current price of 3090s makes them a great deal for building a local AI workstation.
Notes and caveats
- The $4,300 figure is what the builder actually paid for used parts. The parts list totals $6,486 at the prices we listed when we added the build.
- The “case” is an IKEA FJÄLLBO table, so everything runs open-air.
Source
Originally shared on r/LocalLLaMA: 4x 3090 local AI workstation.
Specifications
Full specs
- GPU
- 4× RTX 3090
- CPU
- AMD Ryzen Threadripper PRO 3955WX
- Motherboard
- ASUS Pro WRX80E-SAGE
- Memory
- 128GB DDR4 (Remix Ram)
- Storage
- Samsung 980 Pro 2TB NVMe SSD
- Power supply
- Corsair HX1500i 1500W
- Case
- IKEA FJÄLLBO table (open air)
- Cooling
- ARCTIC Liquid Freezer III
- Form factor
- open-frame
- GPU power
- 1,400W rated
Keep browsing