Mid-range build · tower · New + used parts
V100 Research Workstation
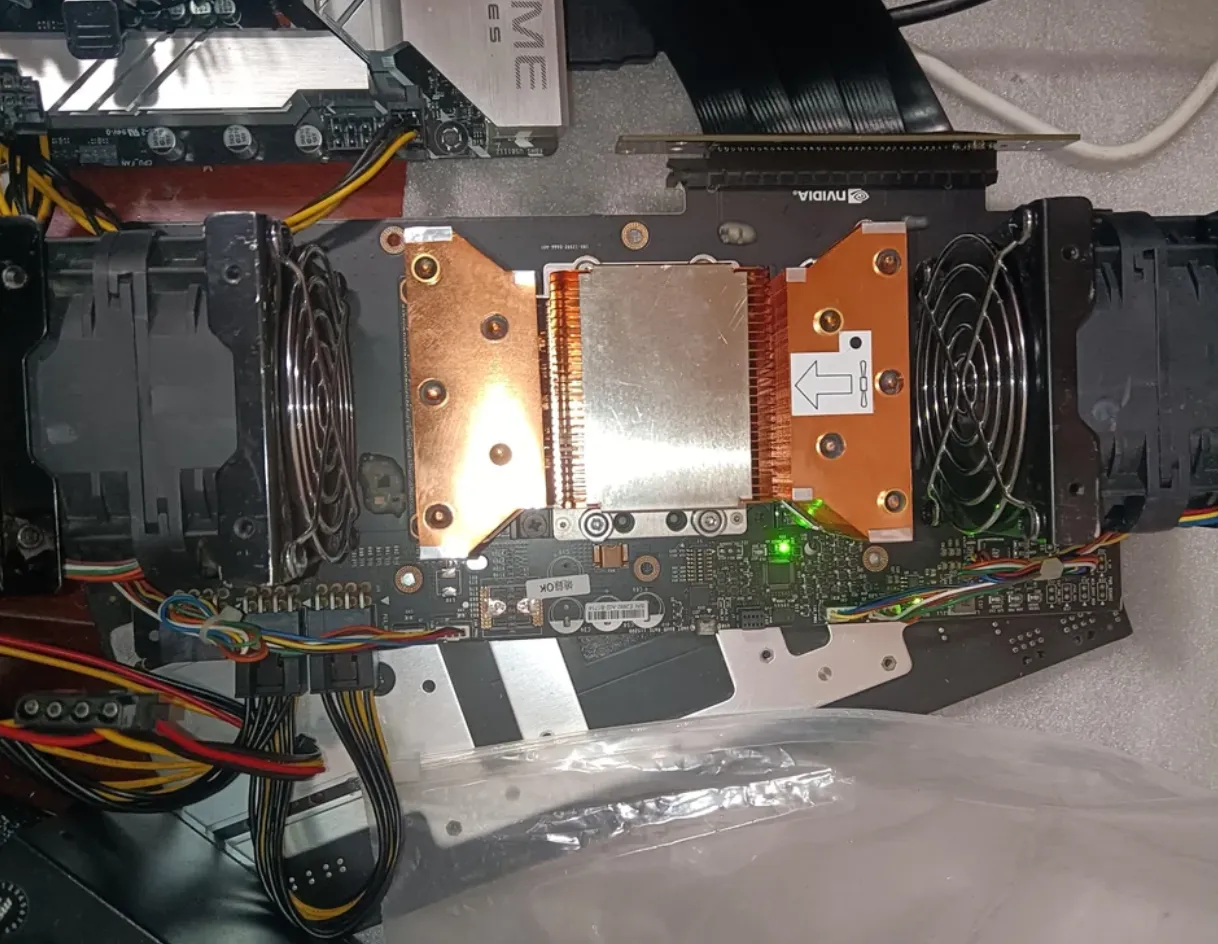
NVIDIA V100 adapted GPU server
Built by Llama Builds · Updated
- Total cost
- $3,686
- VRAM
- 32GB
- GPUs
- 1
- System RAM
- 64GB
What can this build run?
With 32GB of VRAM across one GPU, this build comfortably runs models up to Qwen3.6 35B-A3B (Q5_K_M, ~105 tokens/sec). Our top all-round pick for it is Qwen3.8 27B at Q6_K (~25 tokens/sec).
Parts list
Every part in the V100 Research Workstation
We may earn a commission when you buy through links on this page. It never changes what we recommend. How we make money
| Part | Price | Buy |
|---|---|---|
GPU NVIDIA Tesla V100 32GB SXM2 | $529 | eBay |
Storage Samsung PM9A3 3.84TB NVMe SSD | $390 | Amazon |
Power Supply Seasonic Prime TX-1000 1000W 80+ Titanium | $479 | Amazon |
Case Unspecified case The original listing did not name a case. | — | |
CPU Cooler Noctua NH-U14S TR4-SP3 | $89 | Amazon |
Accessories SXM2 to PCIe adapter | $120 | eBay |
CPU Intel Xeon W-3275 | $740 | eBay |
Motherboard ASUS Pro WS C621-64L SAGE | $899 | eBay |
Memory Samsung M393A8G40AB2-CWE 64GB DDR4-3200 ECC | $440 | eBay |
| Total | $3,686 |
Prices at time of build (2025); check current prices.
Capability
Models this build runs well
Estimated for a single user with 8K context. Best quantization that fits, ranked by our capability score.
Best overall · also coding, reasoning, vision
Qwen3.8 27BQ6_K · ~25 tokens/sec
Runner-up · also fastest, largest that fits
Qwen3.6 35B-A3BQ5_K_M · ~105 tokens/sec
| Model | Quant | Speed | Fit |
|---|---|---|---|
| Qwen3.8 27B | Q6_K | ~25 tok/s | Runs well |
| Qwen3.6 35B-A3B | Q5_K_M | ~105 tok/s | Runs well |
| Gemma 4 31B | Q5_K_M | ~25 tok/s | Runs well |
| Gemma 4 26B A4B | Q6_K | ~84 tok/s | Runs well |
| gpt-oss-20b | MXFP4 | ~100 tok/s | Runs well |
| Qwen3.5 9B | Q8_0 | ~51 tok/s | Runs well |
| Gemma 4 E4B | Q8_0 | ~58 tok/s | Runs well |
| Phi-4 | Q8_0 | ~36 tok/s | Runs well |
The build
About this build
A deep learning research workstation built around a data-center V100 32GB SXM2 module on a PCIe adapter, paired with a Xeon W-3275 and ECC memory for 24/7 operation.
Why this build
This high-performance research station is built around the NVIDIA V100 32GB SXM2 for deep learning research and model training. The V100 is a data-center SXM2 module, so it runs here on an SXM2-to-PCIe adapter that lets it sit in a standard workstation motherboard.
The rest of the build uses enterprise-grade components for 24/7 operation, including a Xeon W-3275 and ECC memory.
Notes and caveats
- The original listing did not specify a case.
- The Noctua NH-U14S TR4-SP3 is designed for AMD TR4 and SP3 sockets, while the Xeon W-3275 uses LGA3647. Check cooler compatibility before copying this build; Noctua also makes an LGA3647 version of the NH-U14S.
Specifications
Full specs
- GPU
- V100 32GB
- CPU
- Intel Xeon W-3275
- Motherboard
- ASUS Pro WS C621-64L SAGE
- Memory
- 64GB DDR4-3200 ECC (Samsung M393A8G40AB2-CWE)
- Storage
- Samsung PM9A3 3.84TB NVMe SSD
- Power supply
- Seasonic Prime TX-1000 1000W 80+ Titanium
- Cooling
- Noctua NH-U14S TR4-SP3
- Form factor
- tower
- GPU power
- 300W rated
Keep browsing